


About Me
I'm an AI/LLM Engineer building production-grade NLP systems at SproutsAI, having recently completed my B.Tech in CSE (Honors in AI & ML) from Vishnu Institute of Technology.
My engineering focus is bridging the gap between open-source models and live environments — through agentic workflows, high-performance RAG pipelines, and scalable inference infrastructure.
 Hugging Face
 Qdrant
 FastAPI
 PyTorch
 LangChain
 Docker
 Neo4j
 vLLM
Education
B.Tech in CSE (Honors in AI & ML)
Vishnu Institute of Technology, Bhimavaram
Intermediate – MPC
Sasi Junior College, Rajahmundry
SSC
Ravindra Bharathi High School, Rajahmundry
What I Build
LLM Deployment
Deploy & benchmark open-source LLMs (Phi-4, Qwen2.5-72B, Qwen3.5-35B) on NVIDIA DGX via vLLM + Docker.
RAG Pipelines
Design end-to-end retrieval-augmented generation with vector search, embeddings & prompt engineering.
Model Evaluation
Benchmark LLMs against production use cases — resume parsing, email generation — with quantization (AWQ).
Semantic Search
Vector DB migrations (MongoDB → Qdrant), embedding model evaluation & false positive reduction at scale.
Agentic Sourcing
Multi-source web retrieval (Tavily, Exa AI, DuckDuckGo) & GitHub enrichment pipelines for candidate discovery.
Full Stack Apps
React, Next.js, FastAPI — building end-to-end web applications with modern frontend & scalable backends.
AI Engineering & Full Stack
Core Tech Stack & Tools








AI & Engineering Domains
Models Worked With
Applied Capabilities & Engineering Solutions
Impact by the Numbers
My Experience
SproutsAI2 Roles · Progression
Machine Learning Engineer - AI/NLP
LLM Benchmarking & DGX Spark Infrastructure
- Architected and deployed an LLM benchmarking suite on NVIDIA DGX Spark (vLLM, Docker) evaluating Qwen3.6-35B-A3B MoE, Qwen3.5, Gemma 4, Phi-4, and Qwen2.5-72B-AWQ against Gemini; shipped Qwen3.6-35B-A3B, ~39% faster than Qwen3.5 (~60% under concurrent load) and ~26% faster than Gemma 4.
- Executed model quantization experiments (Qwen2.5-72B-AWQ) within DGX Spark's 128GB unified memory constraint; built local inference pipelines eliminating reliance on cloud APIs (SageMaker) to cut compute costs and ensure data privacy.
Match Parser & Candidate Recommendation Engine
- Diagnosed inflated match scores on empty and sparse candidate profiles; consolidated scattered scoring logic into a single evidence-based, queue-driven (RabbitMQ) Match Parser pipeline, cutting false positives by 20%.
- Designed and built a feedback-driven candidate recommendation engine: multi-vector Qdrant retrieval (E5 embeddings, fused with RRF) driven by recruiter thumbs-up/down signals, re-ranked by Gemini 2.5 Flash with per-candidate reasoning.
Agentic Autosourcing & Profile Enrichment
- Expanded autosourcing beyond Elasticsearch-indexed ATS profiles to 8 new web-search and people-data sources (Exa, Tavily, Apollo, Google, DuckDuckGo) with must-have/nice-to-have ranking, cutting low-quality candidate reviews by 40%.
- Built a GitHub enrichment agent that identifies technical skills with confidence scores backed by repo- and commit-level evidence, cross-referencing candidate portfolios and resumes.
NLP/AI Engineer Intern
Vector Search Migration & Embedding Microservices
- Executed zero-downtime production vector search migration from MongoDB to Qdrant across 5 NLP repositories (10K+ daily queries), validating result parity.
- Deployed containerized FastAPI-based embedding service (Hugging Face SentenceTransformer) with backward-compatible validation for scalable semantic matching.
Candidate Filtering & Profiling Pipelines
- Built candidate filtering pipeline (4 rule-based filters, 3 LLM smart labels) across autosourcing and enrichment, reducing early-stage candidate noise by ~80% and cutting irrelevant profiles reaching recruiters by 30%+.
- Built and deployed NLP profile enrichment agents for skill extraction, job title normalization, and achievement detection using embeddings and LLMs.
Distributed Event-Driven Pipelines
- Engineered real-time, distributed queue pipelines using RabbitMQ and Elasticsearch to ingest and process large-scale candidate data with low latency.
Full-Stack Developer Intern| Care Automate
Pipeline Development
- Developed React.js frontend and Express.js backend with MongoDB storage.
- Built and productionized Speech-to-Text and document extraction pipelines.
Production Reliability
- Integrated AI models into backend services while optimizing for latency and production stability.
Community Manager & ML/DL Developer| Nexus Sparks
Technical Mentorship
- Assisted community members in mastering ML & DL through workshops, tutorials, and one-on-one mentoring.
- Provided constructive feedback on ML and DL projects and helped troubleshoot code issues.
Community Engagement
- Engaging with the community to provide technical support, answer questions, and foster a positive learning environment.
- Organizing ML and DL learning sessions and promoting a culture of continuous skill development.
Teaching Aid| StudyOwl & VIT
Peer Mentorship
- Assisting peers and juniors in mastering full-stack development (React.js, Node.js, and Express).
- Providing mentorship and guidance through coding exercises, project-based learning, and hands-on labs.
Technical Workshops
- Organizing and conducting workshops and study sessions to help students grasp full-stack development.
My Projects
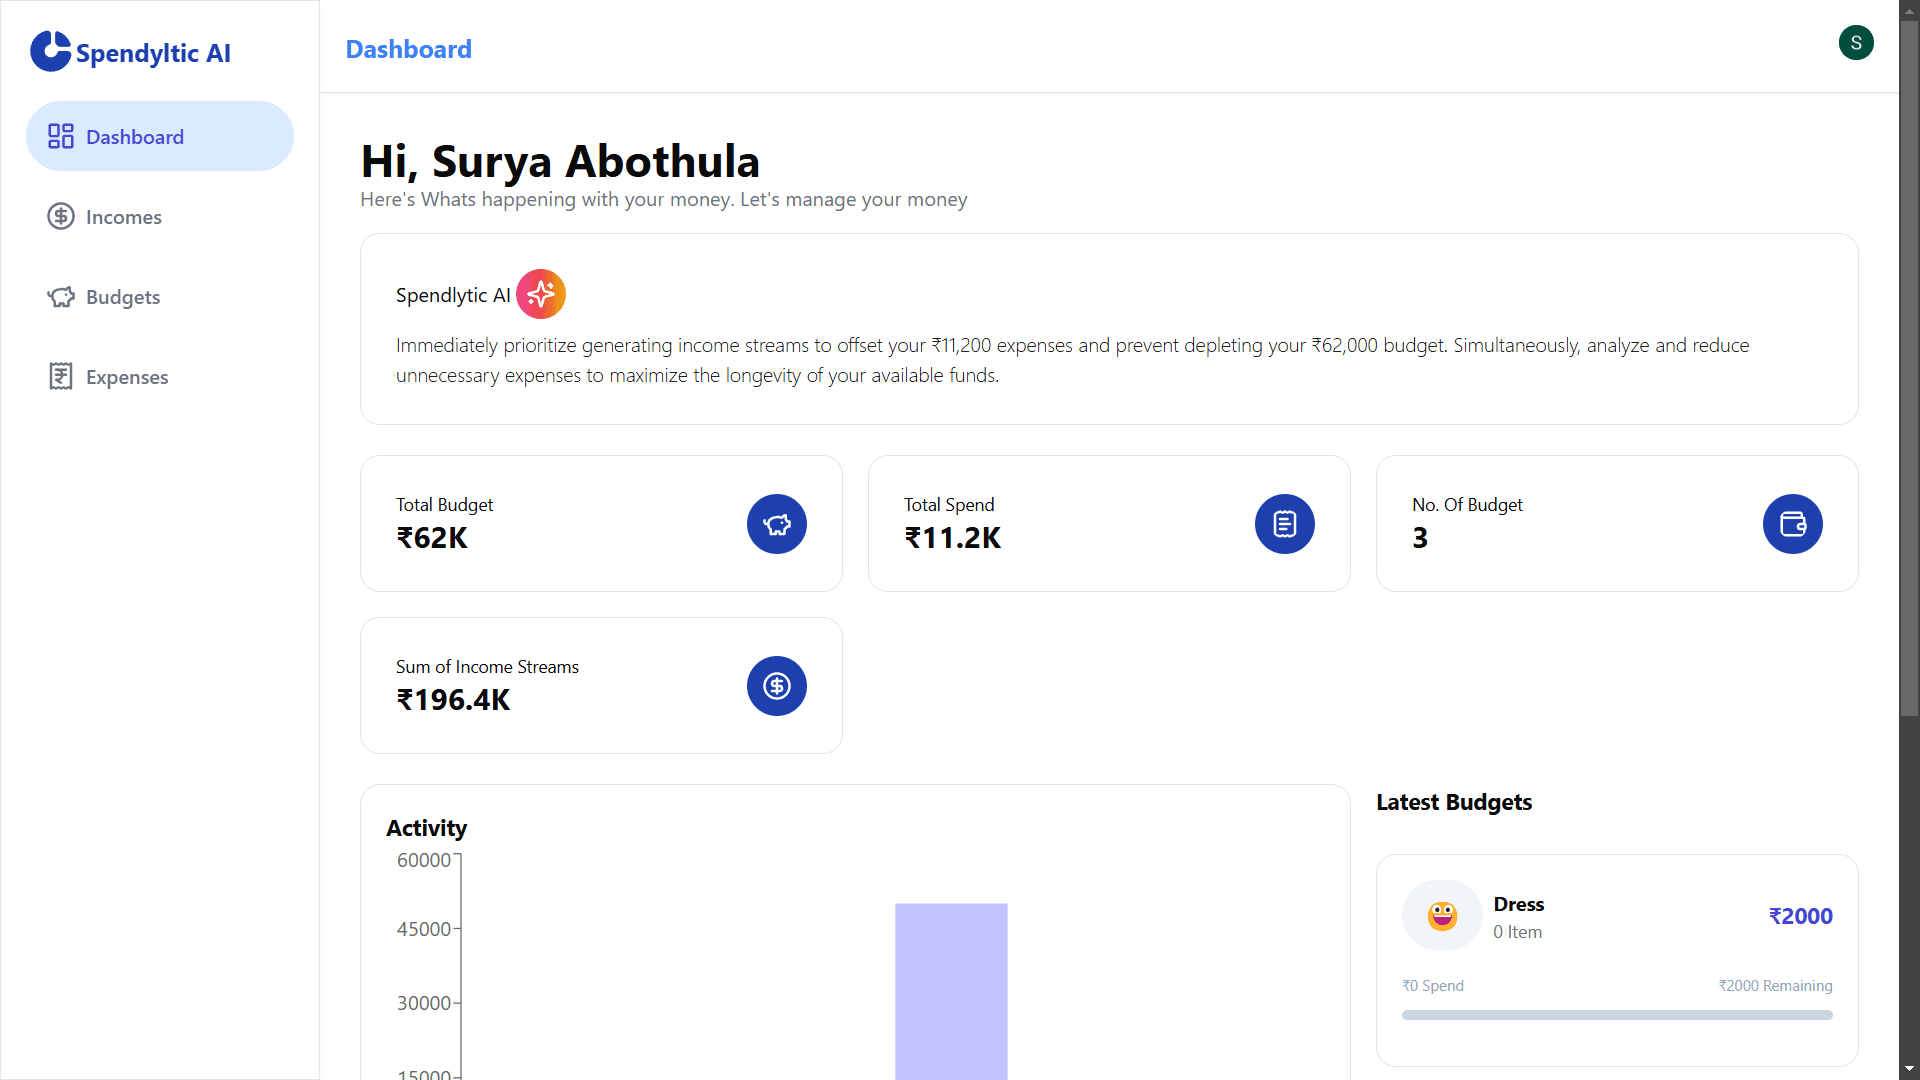
QEventGraph
Event-graph observability framework for quantum programs enabling non-intrusive execution replay. Built dual-relationship graph model (NEXT + QUBIT_DEP) processing 1000+ events with O(n) complexity. Full-stack system with FastAPI + Neo4j backend and interactive React/Cytoscape.js frontend.
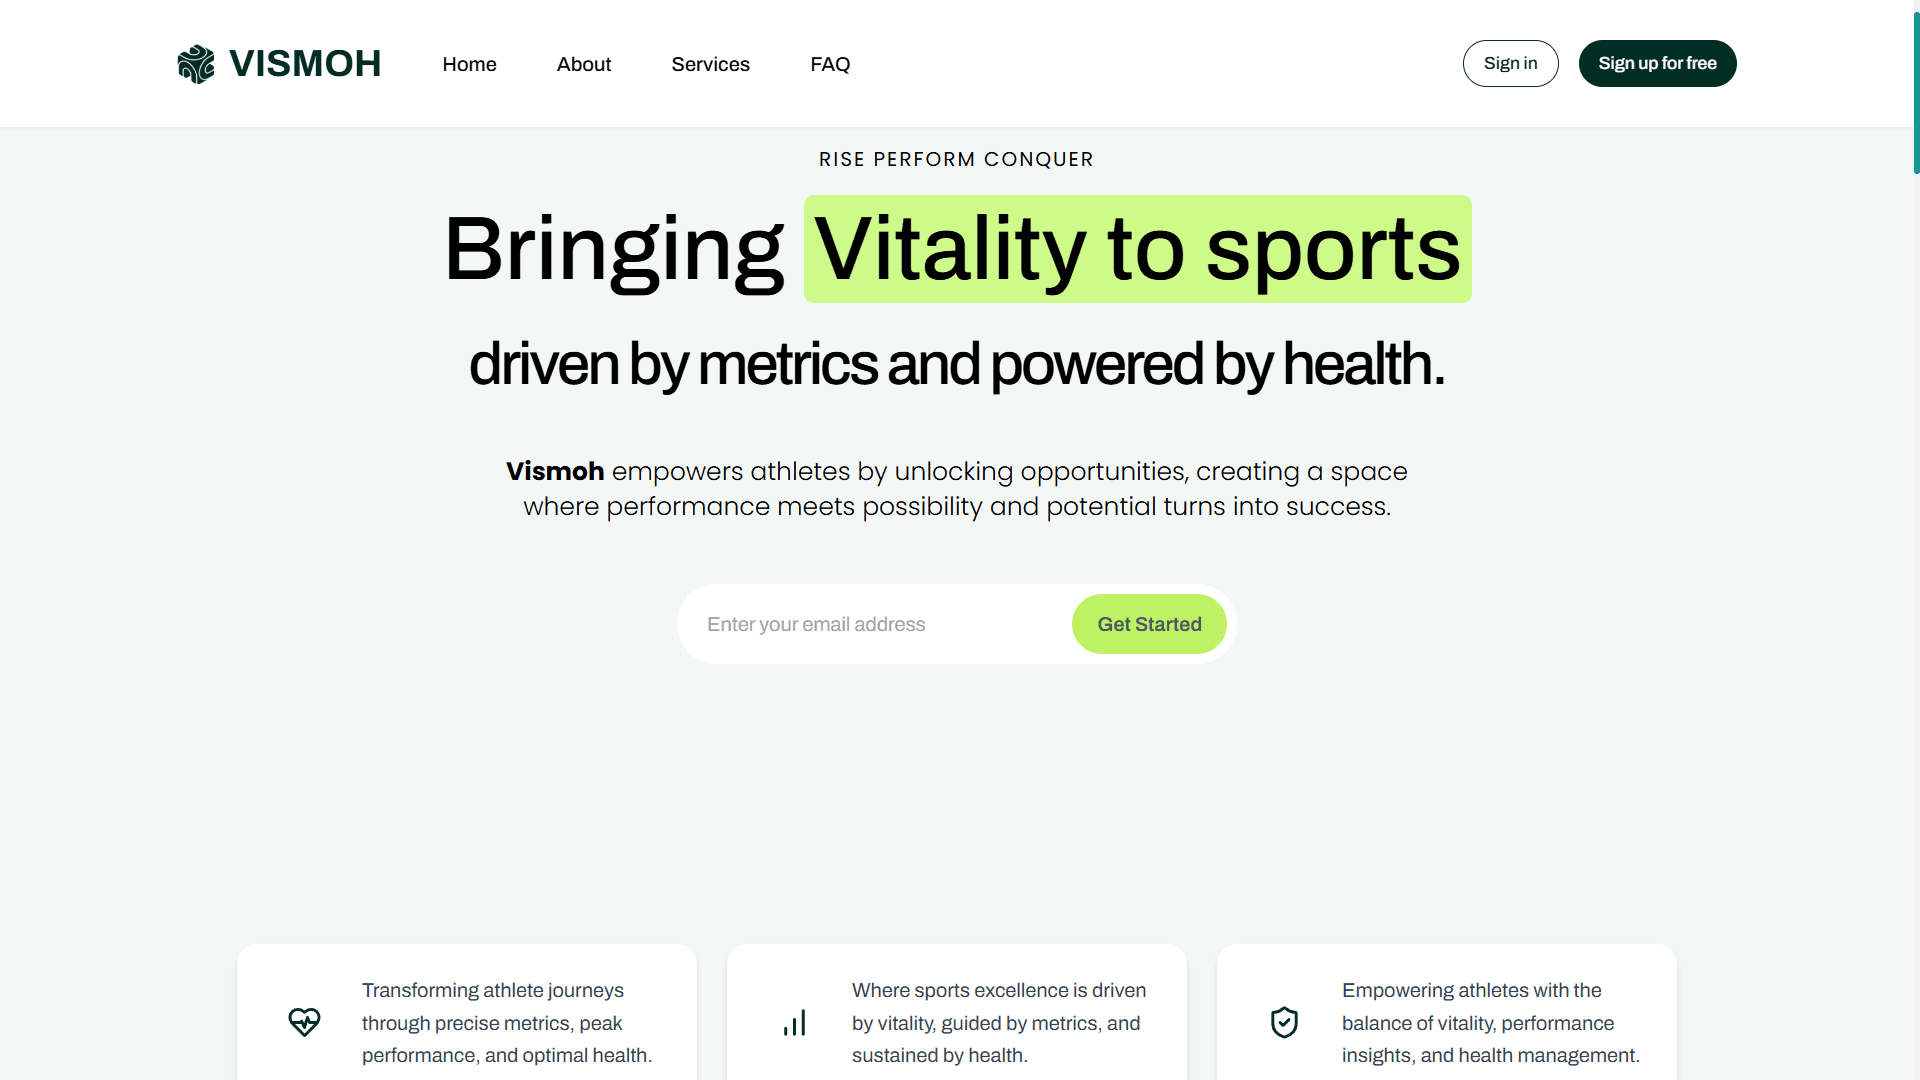
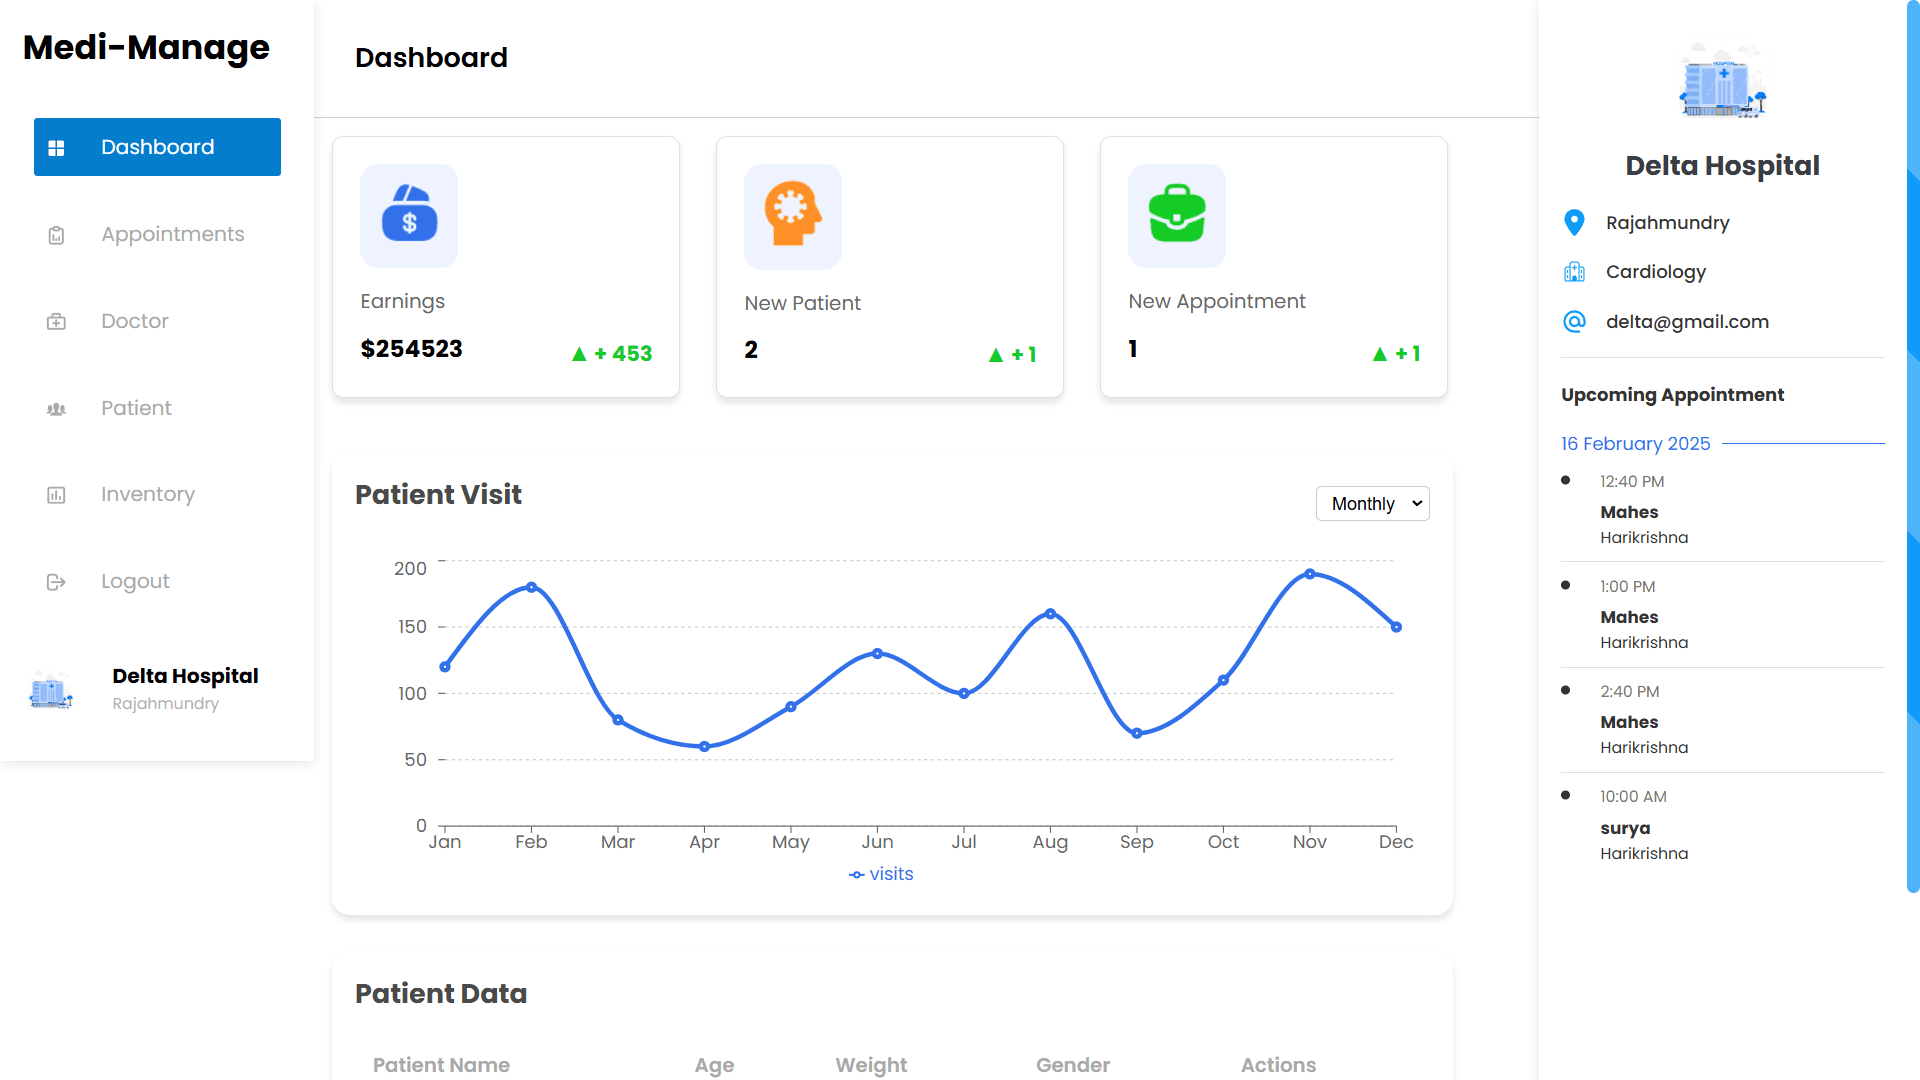
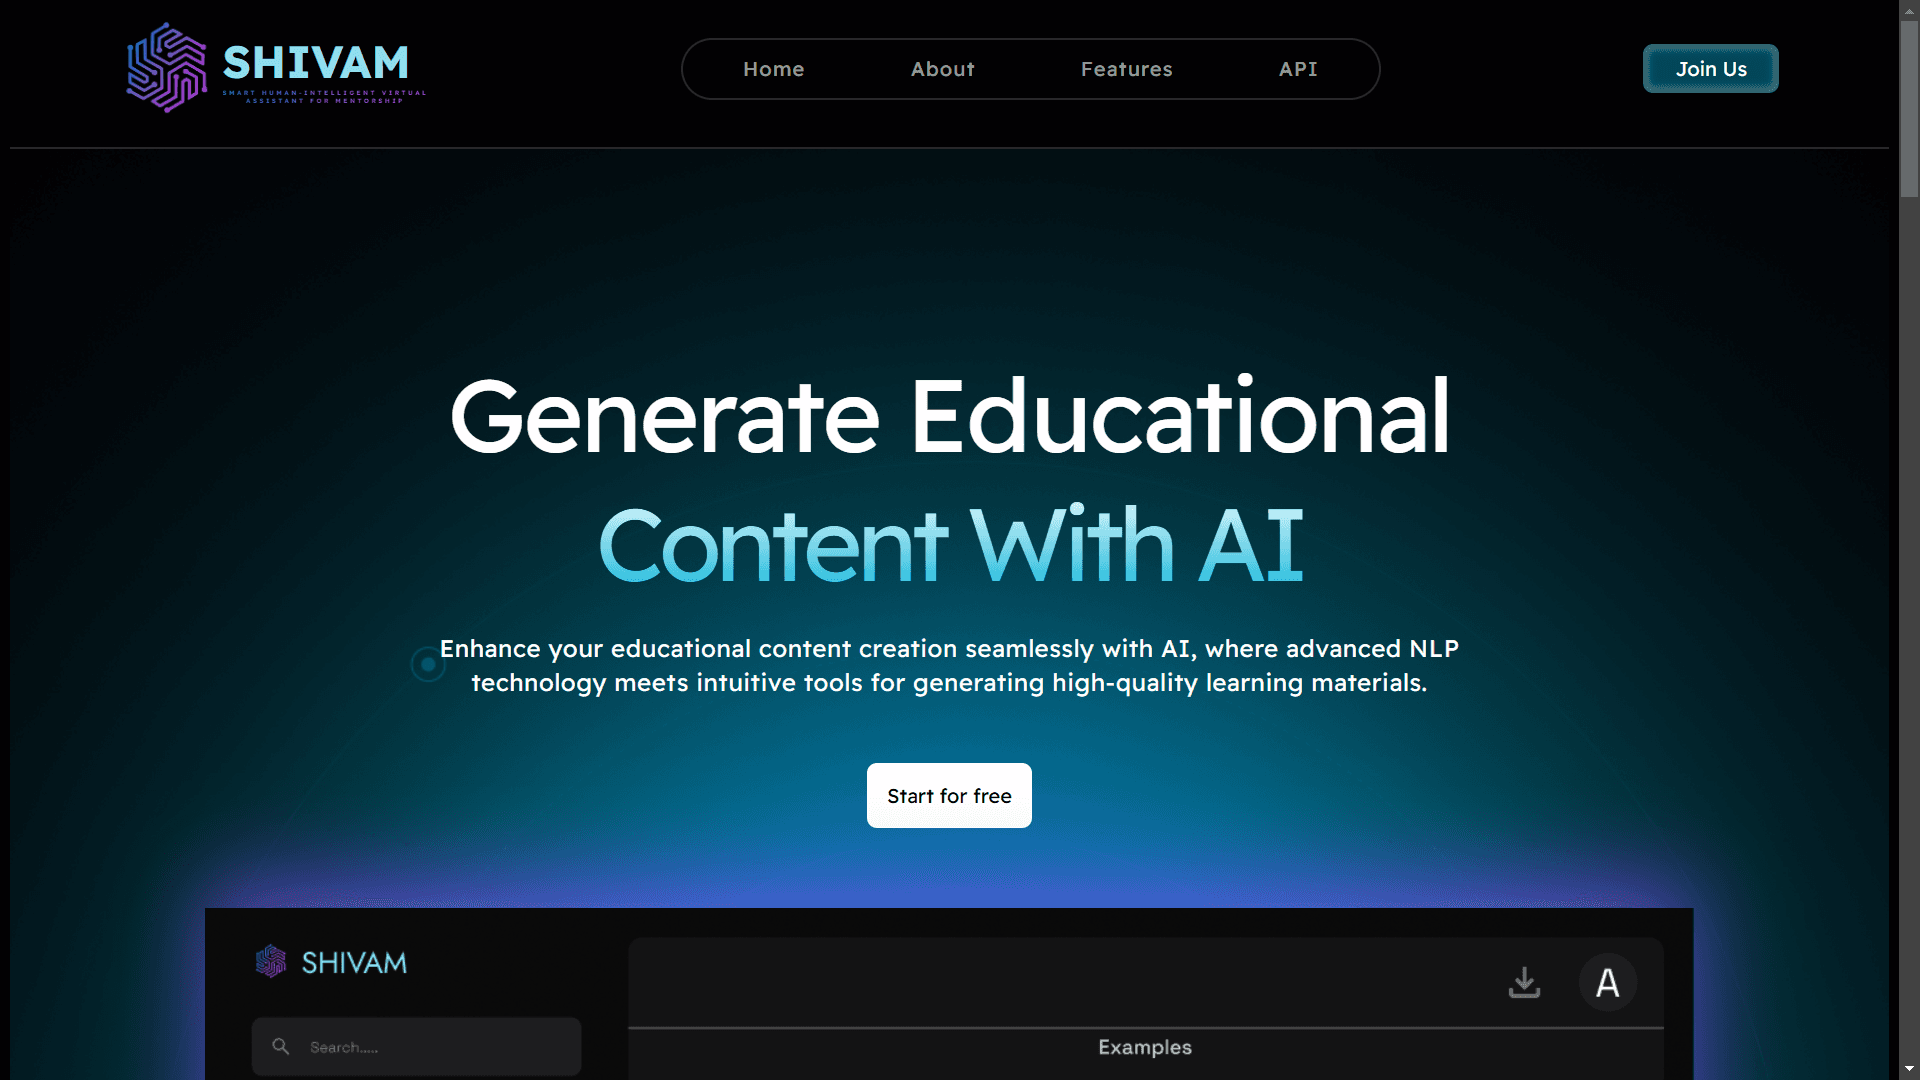
DSA Tracker
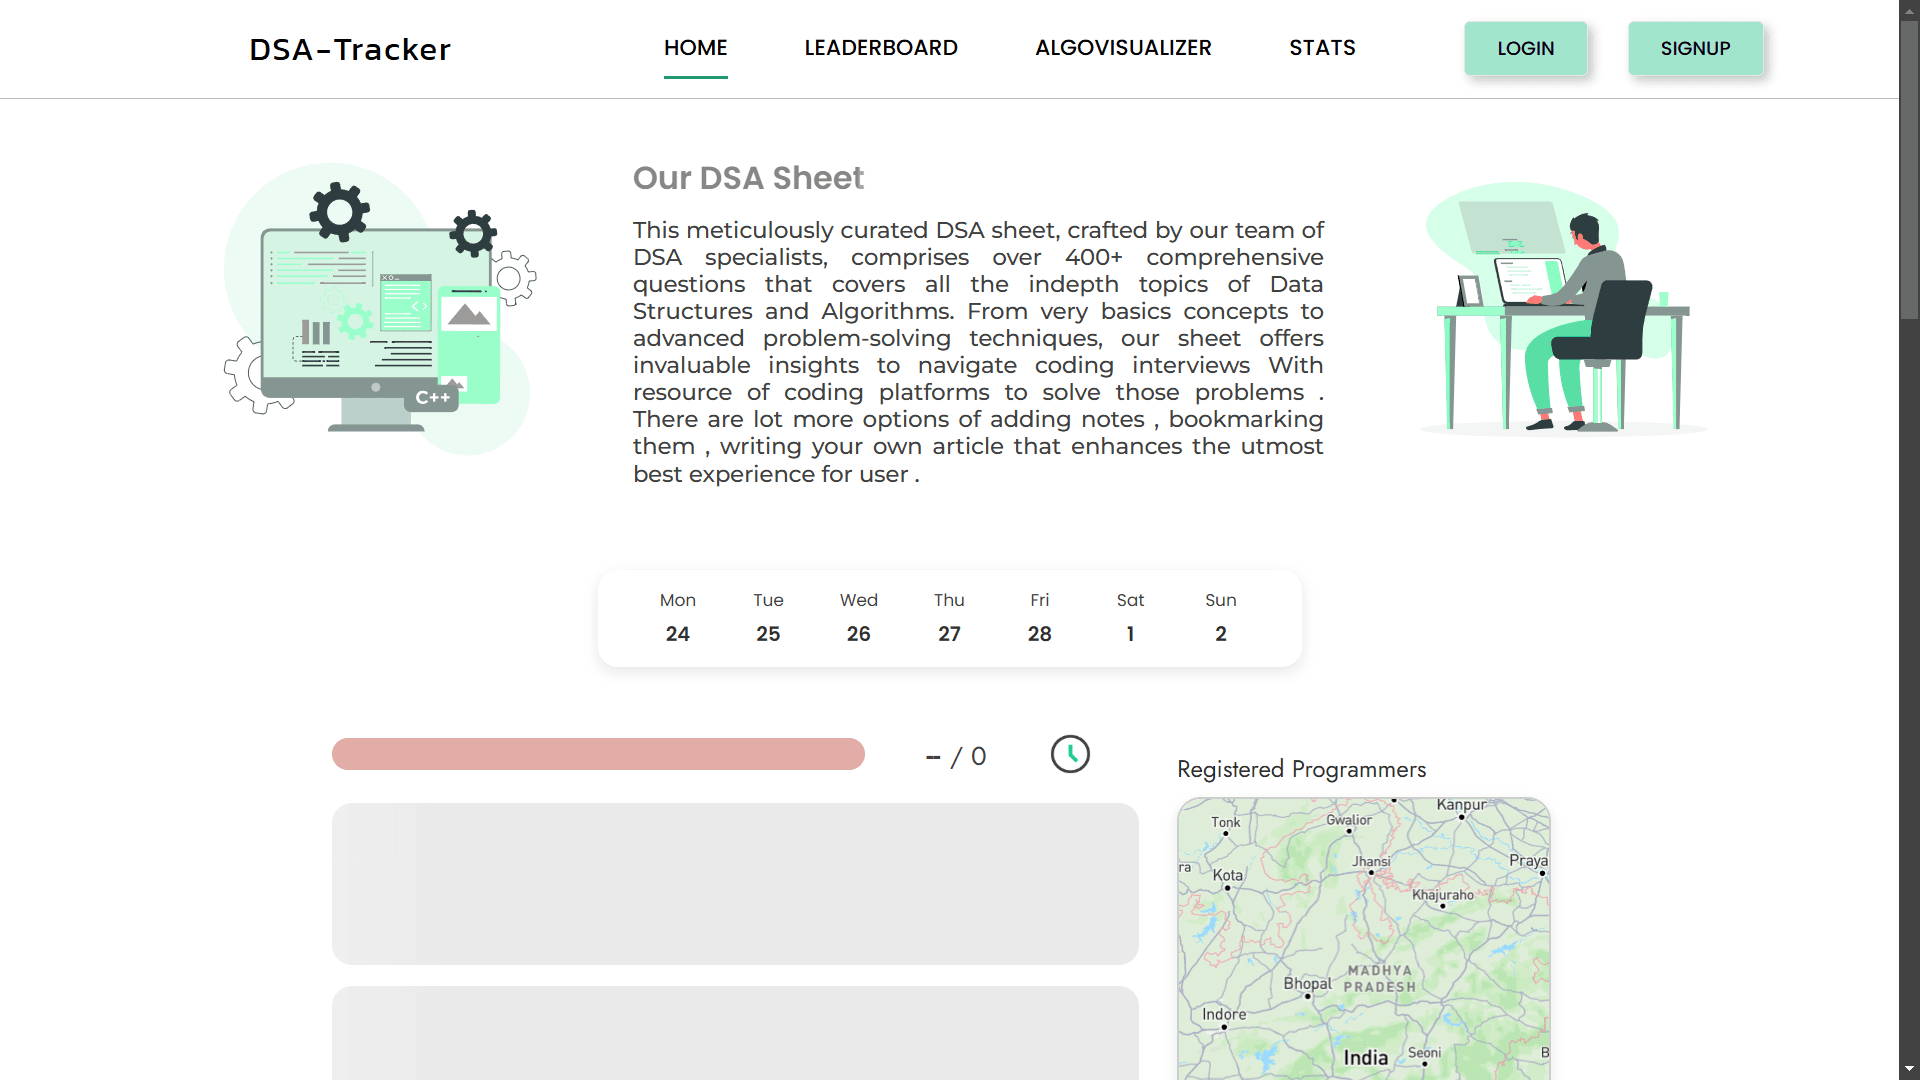
Comprehensive platform for managing and tracking your DSA journey with an intuitive interface and structured progress monitoring.
Technical Writing
Sharing practical AI engineering and Deep Learning insights.
Explore the fundamentals of Deep Learning, its history, key concepts, and why it is transforming industries. This article sets the foundation for understanding neural networks and deep learning models.
Dive into Linear Regression and the Perceptron algorithm. Understand how these fundamental techniques are used in machine learning to make predictions and classify data effectively.
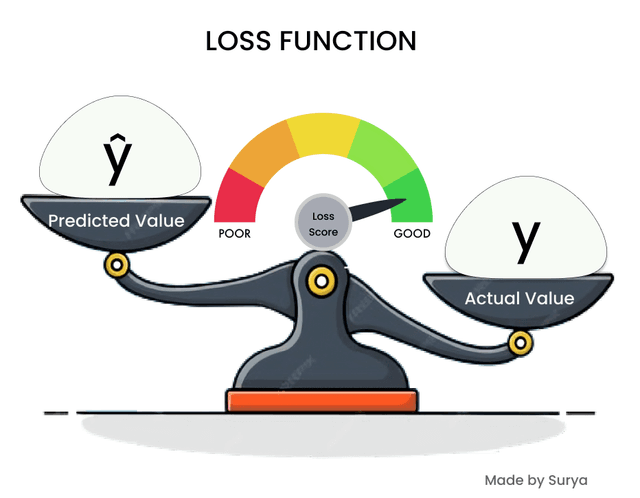
Learn the importance of Loss Functions and how Gradient Descent optimizes neural networks. This article covers cost functions, backpropagation, and techniques to improve learning efficiency.
Achievements
🏆 Star Performer Award (Employee of the Month)
SproutsAI
Recognized for exceptional initiative and driving major engineering milestones within the first month of joining the team. Awarded for consistently exceeding performance targets and taking on responsibilities beyond the standard job description.
- Executed Vector Search migration from MongoDB to Qdrant, including full testing and deployment.
- Implemented the core Ranking Algorithm and integrated Custom/Smart Labels for auto-sourcing improvements.
- Drove geo-code cost mitigation efforts and aligned Resume Parse formatting with backend architecture.
4th Place — GDG HackATron 2025
Google Developer Groups
Placed 4th among 100+ teams for VISMOH — an AI-integrated sports management platform featuring NLP-powered dietary analysis.
Special Appreciation — DeMux Hackathon
DeMux
Recognized for architecting an NLP and AI-based EdTech solution designed for personalized learning pathways.
Contact Me
Contact Details
Building production AI systems and always happy to discuss AI engineering, LLM infrastructure, and backend platforms.